Nobody Is Listening on Port 8125

Founding engineer at yeet, working on kernel-side observability and the tooling around it. I write about eBPF, Linux internals, and why your telemetry bill looks the way it does.
There's a Fedora box on my desk named stick. An app on it has been firing
StatsD datagrams at 127.0.0.1:8125 ten times a second for about a week
now, the way apps have done since Etsy taught everyone to in 2011.
Nothing is listening on 8125.
$ ss -lun | grep 8125
$
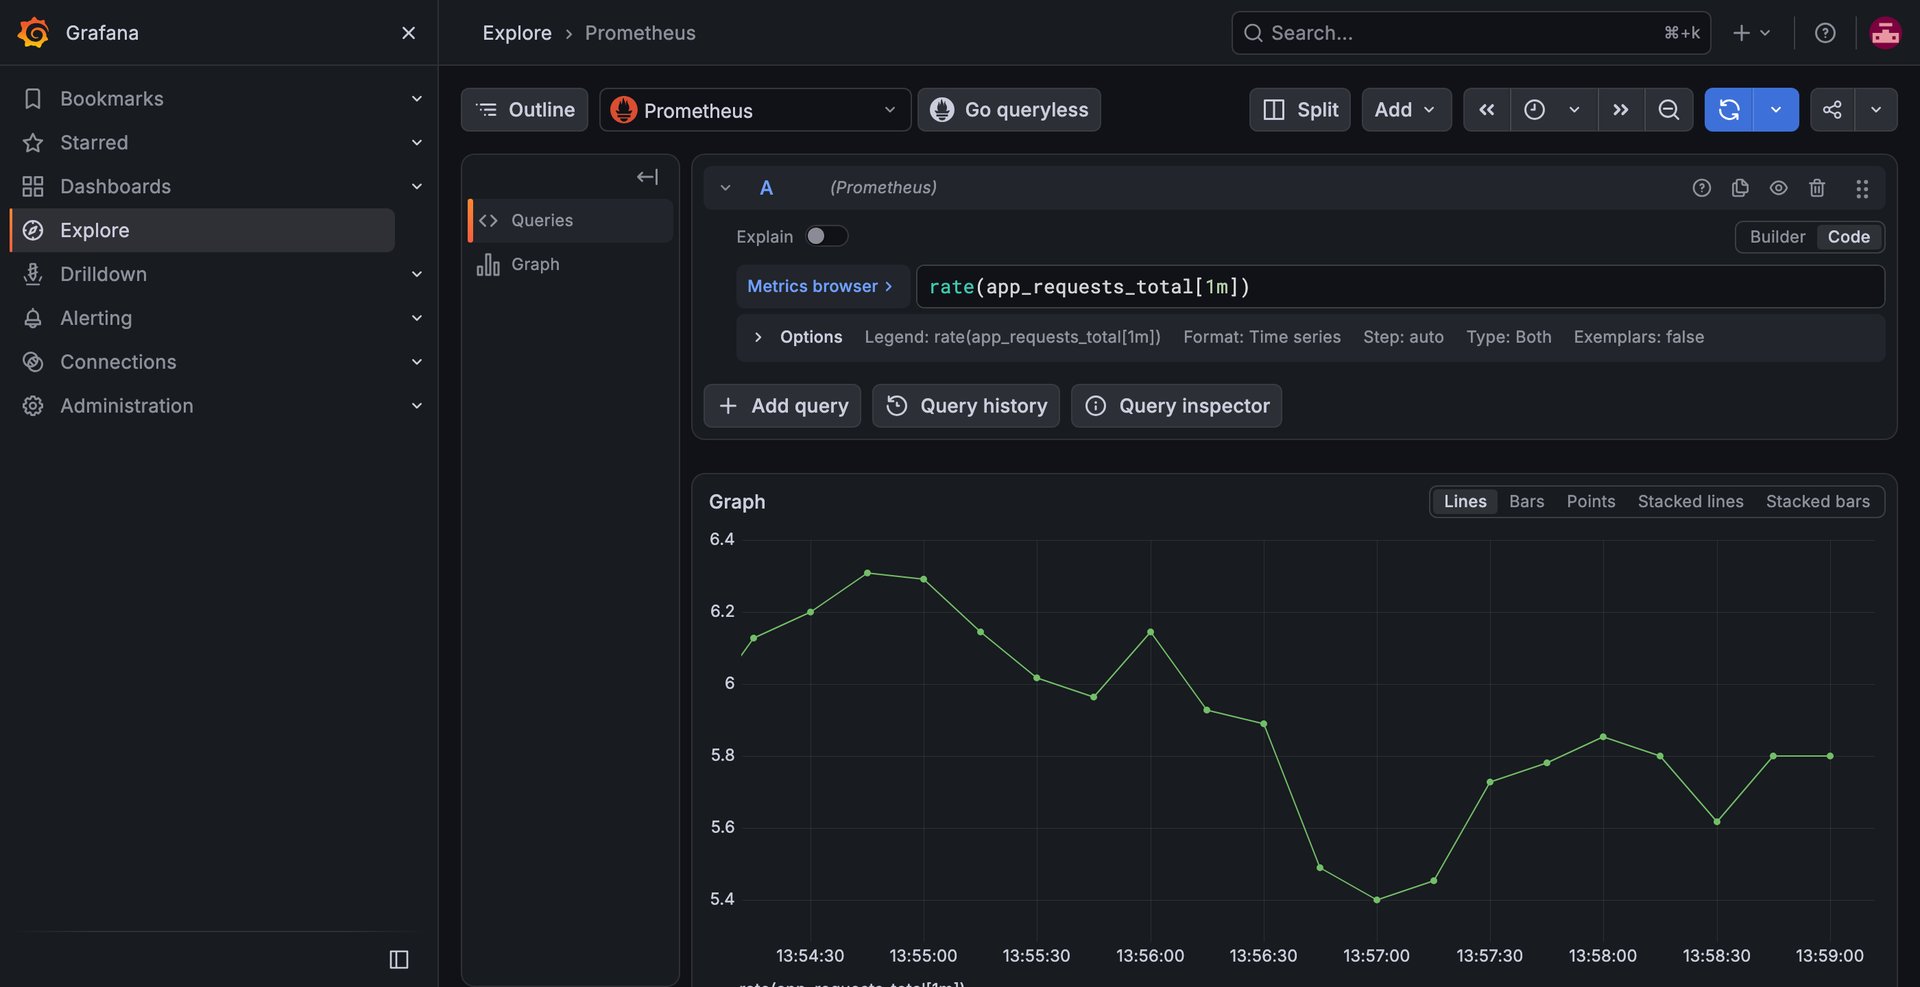
Grafana has the request rate anyway.
This is the first post in a series where we go down the list of exporters
everyone runs next to Prometheus and replace them, one at a time, with a
yeet script. The pitch for the series is short: you do
not need fifty exporters in six languages, each with its own port, its own
config format, and its own opinion about vendoring. You need one binary
that can read the kernel. We're starting with statsd_exporter because it's
the one where the replacement stops being the same thing and turns into
something kind of better.
TL;DR
statsd_exporter is a translator. Your app pushes StatsD lines at it over
UDP, it holds them as Prometheus metrics, Prometheus pulls. It's maintained
by the Prometheus project itself, so this is an official piece of the stack
we're pulling out.
We replaced the listener with an eBPF program that watches port 8125 at the
traffic control layer of every interface, and a JavaScript decoder that
turns the lines into Prometheus families. The app keeps doing fire-and-forget
UDP. Nothing changes on the app. Nothing gets installed on the host except
yeet. And the metrics show up whether or not anyone is there to receive
the datagrams.
You'll learn:
- Why a StatsD receiver is just a packet sniffer with a socket in front of it.
- The 165 lines of C that read the wire, and why the same mechanism works for any line protocol you point it at. Redis, memcached and Graphite are later posts in this series and they reuse this probe unchanged.
- How
yeet:telemetryturns a script into a Prometheus target without the script ever touching a socket. - What you give up, because you do give up a couple things.
The whole thing is open source. To run it on your own boxes:
Ok so what does statsd_exporter actually do
Less than you'd think. It binds a UDP socket, reads datagrams, splits them on newlines, and parses lines that look like this:
app.requests:1|c
app.queue.depth:22|g
app.request.time:143|ms
app.users:20|s
app.errors:1|c|@0.1|#service:api,region:us
Then it keeps a counter, gauge, histogram or set per name, runs the names
through a YAML mapping file so your dots turn into labels, and serves the
whole thing on :9102/metrics. That's it. That's the exporter. It's a
perfectly good exporter and I've run it for years without thinking about it
once, which is about the nicest thing you can say about infrastructure.
But look at what it eats. UDP datagrams. On a well-known port. In a plaintext line format. Usually on the same host as the app. By the time that socket gets the bytes, the kernel has already had them, looked at them, and decided where they go. The listener is the second reader of every packet.
So we asked the first one.
165 lines of C
The kernel half is a tcx program clipped onto the ingress and egress hooks of every interface that's up, loopback included. It does three things: find the transport header, check if either port is one we care about, copy a bounded chunk of the payload into a ring buffer. Done.
/* The ports worth capturing, filled by the script. */
struct {
    __uint(type, BPF_MAP_TYPE_HASH);
    __uint(max_entries, 64);
    __type(key, __u16);
    __type(value, __u8);
} ports SEC(".maps");

static __always_inline int wanted(__u16 sport, __u16 dport)
{
    return bpf_map_lookup_elem(&ports, &sport) != NULL
        || bpf_map_lookup_elem(&ports, &dport) != NULL;
}

static __always_inline int handle(struct __sk_buff *skb, __u8 dir)
{
    /* ... walk Ethernet or raw IP, then IPv4 or IPv6, to the L4 header ... */

    __u16 sport = 0, dport = 0;
    bpf_skb_load_bytes(skb, l4,     &sport, 2);
    bpf_skb_load_bytes(skb, l4 + 2, &dport, 2);
    sport = bpf_ntohs(sport);
    dport = bpf_ntohs(dport);
    if (!wanted(sport, dport))
        return TCX_NEXT;

    /* ... TCP data offset or the 8-byte UDP header, then the payload ... */

    struct wire_event *e = bpf_ringbuf_reserve(&events, sizeof(*e), 0);
    if (!e)
        return TCX_NEXT;
    e->ts        = bpf_ktime_get_ns();
    e->sport     = sport;
    e->dport     = dport;
    e->ifindex   = skb->ifindex;
    e->dir       = dir;
    e->total_len = plen;
    e->captured  = cap;
    if (bpf_skb_load_bytes(skb, poff, e->data, cap) < 0) {
        bpf_ringbuf_discard(e, 0);
        return TCX_NEXT;
    }
    bpf_ringbuf_submit(e, 0);
    return TCX_NEXT;
}
That ifindex is there for a reason. A packet on loopback goes through
the egress hook on lo, and then, because the kernel just hands it right
back to itself, through the ingress hook on lo. Same bytes, two events.
TCP you can dedupe on the sequence number. UDP has no sequence number. So
on loopback the collector keeps the egress copy and drops the other one,
and every datagram counts exactly once:
if (ev.dir === DIR_INGRESS && ev.ifindex === lo) return;
Look at the ports map too. There's no port number anywhere in the C.
The script fills the map at startup from its arguments, and 8125 is contentionally
what statsd used, but there's no reason why it couldn't be anything else.
Because the kernel side has no idea what StatsD is, the same mechanism covers anything else that speaks
a line protocol on a known port. It matches a port and copies up to 512
bytes. Parsing is a JavaScript problem, and JavaScript is cheap. The
collector on stick already runs the Redis, memcached and Graphite
decoders off this one probe, each with its own flag, and those get their
own posts. The next protocol costs a port number and a decoder.
Everything else stays in the kernel. ACKs, TLS, your Zoom call, none of it
ever crosses into userspace. And the program returns TCX_NEXT on every
path, so it never drops or rewrites a packet. It reads. That's the whole
job.
yeet loads it from a script with
yeet:bpf. The attach target is
whatever the system graph says is up:
import { BpfObject, HashMap, RingBuf } from "yeet:bpf";

const { data } = await yeet.graph.query(`{ network_interfaces { index is_up } }`);
const tcx = { kind: "tcx", ifindex: data.network_interfaces.filter((i) => i.is_up).map((i) => i.index) };

const control = await new BpfObject({ exe: "../bpf/bin/wire.bpf.o", base: import.meta.dirname })
  .bind("events", { kind: "ringbuf", btf_struct: "wire_event" })
  .bind("ports", { kind: "hash" })
  .attach("on_ingress", tcx)
  .attach("on_egress", tcx)
  .start();

const ports = new HashMap(control, "ports");
for (const port of [8125, 8126]) await ports.update(port, 1);   // from yeet.args, really

await new RingBuf(control, "events").subscribe(onEvent, () => dropped.inc());
btf_struct: "wire_event" is the entire deserializer. The daemon reads the
struct layout out of the object's BTF and hands onEvent a plain object
with sport, dport, data and friends already on it. Same trick in the
other direction for the map: update(8125, 1) is a __u16 key and a
__u8 value because the C said so. We did not write a byte parser. We're
never going to write a byte parser.
The decoder is boring on purpose
Here's the StatsD half with the plumbing cut out:
request(ev, bytes) {
  this.datagrams.inc();
  for (const line of latin1(bytes).split("\n")) {
    const m = /^([^:]+):([^|]+)\|([a-z]+)(?:\|@([0-9.]+))?(?:\|#(.*))?$/.exec(line.trim());
    if (!m) { this.lines.labels({ status: "invalid" }).inc(); continue; }
    const [, rawName, rawValue, type, rate, tags] = m;
    const name = rawName.replace(/\./g, "_");
    const labels = parseTags(tags);          // #service:api,region:us
    const sample = 1 / (Number(rate) || 1);  // @0.1 counts for ten
    this.#apply(name, type, rawValue, Number(rawValue), labels, sample);
  }
}
#apply is a switch on the type letter. c bumps a counter by
value * sample. g sets a gauge, or nudges it if the value came with a
sign. ms, h and d observe a histogram, with milliseconds scaled to
seconds. s throws the value in a set and publishes the size. That's the
StatsD spec. All of it. It fits on a napkin.
Families get created the first time a name shows up, which is the part
statsd_exporter makes you do in YAML ahead of time:
#family(name, type, labels) {
  const key = `${type}:${name}`;
  let f = this.#series.get(key);
  if (!f) {
    const opts = { help: `StatsD ${type} ${name}, read off the wire.`, labels: labels.names };
    if (type === "histogram") opts.buckets = LATENCY_BUCKETS;
    f = this.telemetry[type](name, opts);
    this.#series.set(key, f);
  }
  return f;
}
this.telemetry is a
Telemetry registry. The
first app.errors line that shows up with #service:api,region:us on it
locks in the label set for app_errors_total. A later line with different
tags gets counted under statsd_exporter_lines_total{status="rejected"}
instead of taking the collector down. Same rule the real exporter has, we
just didn't make you write it in a config file.
Ok but the isolate can't open a socket
Correct. The isolate a yeet script runs in cannot bind a port. It also
can't fetch, which we went on about last time
and still think is the best thing about it. The only listeners anywhere in
this picture belong to the daemon, and the daemon speaks HTTP and
WebSocket and that's the list.
So how does Prometheus scrape the thing?
Two pieces. The collector runs as a SharedWorker and calls
telemetry.serve(), which answers snapshot requests over a message port.
The scrape endpoint is a separate script, and it's tiny:
import { render } from "yeet:telemetry";
import { emit } from "../../lib/emit.js";
import { pick, upAs } from "../../lib/snapshot.js";

// Everything the wire collector holds that is not another protocol's.
const OTHERS = ["redis_", "memcached_", "graphite_"];
emit(await render({ worker: "../../lib/collectors/wire.js" }, ({ worker: w }) => ({
  ...upAs(w, "statsd_exporter_up", "1 when the wire collector answered."),
  ...Object.fromEntries(Object.entries(w).filter(([k, f]) =>
    k !== "yeet_worker_up" && !OTHERS.some((p) => k.startsWith(p)) && !/^Graphite/.test(f?.help ?? ""))),
})));
render({ worker }) connects to the shared worker, asks for its registry,
and hands the families to a function that reshapes them. This one throws
out the series the other decoders on the same probe produced and keeps
the rest under statsd_exporter's name. What comes out gets printed to the
console as Prometheus text format, and the encoder validates it on the way
out so you can't ship a malformed document by accident.
Then yeet service does the bit where a console becomes an HTTP response:
yeet service unit add exporter-swap/gateway -W "http://0.0.0.0:9100"
yeet service unit add exporter-swap/statsd_exporter -I exporters/statsd_exporter/metrics.js --lazy
yeet service mount exporter-swap/gateway -L /statsd_exporter/metrics -t statsd_exporter -p console -T per-connection
A plain GET on /statsd_exporter/metrics spawns a fresh isolate, runs the
script above, streams its console into the response body, and exits. A
scrape is a process that lives for a few milliseconds and never has
network access at any point in its life. Prometheus cannot tell the
difference:
scrape_configs:
  - job_name: statsd
    metrics_path: /statsd_exporter/metrics
    static_configs:
      - targets: ["stick:9100"]
$ curl -s stick:9100/statsd_exporter/metrics
# HELP statsd_exporter_up 1 when the wire collector answered.
# TYPE statsd_exporter_up gauge
statsd_exporter_up 1
# HELP statsd_exporter_udp_packets_total StatsD datagrams seen on the wire.
# TYPE statsd_exporter_udp_packets_total counter
statsd_exporter_udp_packets_total 215702
# HELP app_requests_total StatsD counter app_requests, read off the wire.
# TYPE app_requests_total counter
app_requests_total 129798
# HELP app_errors_total StatsD counter app_errors, read off the wire.
# TYPE app_errors_total counter
app_errors_total{service="api",region="us"} 1296520
# HELP app_queue_depth StatsD gauge app_queue_depth, read off the wire.
# TYPE app_queue_depth gauge
app_queue_depth 22
# HELP app_request_time StatsD histogram app_request_time, read off the wire.
# TYPE app_request_time histogram
app_request_time_bucket{le="0.0005"} 0
app_request_time_bucket{le="0.001"} 0
app_request_time_bucket{le="0.002"} 462
...
app_request_time_sum 19534.094000000434
app_request_time_count 129174
app_errors_total is ten times app_requests_total because the app sends
it with @0.1. The tags turned into labels. The timer turned into a
histogram in seconds. Nobody wrote a mapping file.
tl;dr: the datagram was always the metric. We just stopped needing a process to catch it.
What you give up
Nothing here is magic, so here's the receipt.
You see what this host sends. A real listener sees what arrives. If
your app on host A ships StatsD to a collector on host B, this runs on A
and counts at the source, and Prometheus's instance label tells you
which A. I'd argue that's better. It is definitely different.
Names follow the default mapping. Dots become underscores and that's
it. If you lean on statsd_exporter's mapping language to turn
app.api.us.requests into app_requests{service="api", region="us"},
you'd write that in the decoder instead. Not a lengthy addition but
was outside the scope of this post. Feel free to submit a PR if you
want to add it.
Counters get _total. The registry appends the suffix the way every
Prometheus client library does. statsd_exporter leaves it off unless you
ask. Fix your dashboards or fix the decoder, whichever annoys you less.
512 bytes per datagram. StatsD datagrams are
supposed to fit in an MTU and usually clients send batches way smaller, but
DATA_MAX is a #define if yours don't.
It's plaintext. But so is StatsD. When this series gets to the HTTP exporters that stops being true and we'll talk about the TLS uprobe then.
The end
The listener was never the point. It was the thing that got the datagram out of the kernel and into a process that knew how to count. Now the counting happens right next to the kernel: a program the verifier has signed off on copies the line into a ring buffer, a decoder that fits on one screen does the math, and Prometheus pulls the answer out of a sandbox that has no sockets and gets scraped anyway.
Nobody is listening on 8125. The numbers are fine.
Next up: the nginx exporter you never installed, and why it knows more than the one you did.